A million-document collection does not become manageable because a review team works longer hours. It becomes manageable when eDiscovery automation applies repeatable rules, prioritizes the right material, and documents each decision in a defensible workflow. For legal teams handling investigations, litigation, regulatory requests, or fast-moving discovery deadlines, automation is no longer limited to a review-platform feature. It is an operating discipline.
The objective is not to remove lawyers from discovery. It is to reduce the manual handling that creates cost, inconsistency, and deadline risk, so attorneys can spend more time on relevance, privilege, strategy, and the facts that will matter to the case.
Where eDiscovery Automation Delivers Value
The most useful automation begins well before document review. It starts at intake, when a legal team identifies custodians, data sources, relevant time periods, and preservation requirements. Standardized intake forms, collection checklists, and matter-specific protocols reduce the risk that a critical source is missed or that a collection is performed without a clear record of scope and authority.
During collection and processing, automation can identify file types, extract metadata, de-NIST common system files, detect duplicates, apply date filters, and flag potentially corrupt or password-protected items. These steps help reduce the document population before attorney review begins. The result is not simply a smaller data set. It is a more organized data set with an auditable path from original source to review population.
For matters involving mobile devices, email accounts, collaboration tools, or cloud repositories, the benefit is even more practical. Automated workflows can apply consistent collection settings, preserve metadata, and generate logs that support chain-of-custody documentation. That consistency matters when opposing counsel, a regulator, or the court asks how information was identified, preserved, processed, and produced.
eDiscovery Automation Is Not a Substitute for Legal Judgment
Automation is highly effective at repetitive, rules-based work. It is less reliable when the question depends on context, ambiguity, or legal nuance. A document may contain a responsive term but be irrelevant to the claims. A message may appear nonprivileged until its attachment, recipients, or conversation thread is considered. A technology-assisted review model can prioritize likely responsive documents, but it cannot decide the legal significance of a communication without informed human oversight.
That distinction should shape the workflow. Use automation to organize data, remove obvious waste, identify patterns, and prioritize review. Keep experienced legal professionals in control of coding standards, privilege decisions, issue tagging, quality control, and production calls.
The right level of automation depends on the matter. A narrow employment dispute with a limited set of custodians may benefit most from efficient email threading, deduplication, and targeted search terms. A large regulatory investigation may justify concept clustering, active learning, communication analysis, and continuous review metrics. More technology is not automatically better. The process must remain proportionate to the volume, risk, budget, and production schedule.
The Core Workflows to Automate
A defensible program usually focuses first on the points where manual work is both time-consuming and vulnerable to inconsistency.
Intake, preservation, and legal holds
Automated matter intake can capture custodian details, data locations, case identifiers, deadlines, and handling instructions in a consistent format. Legal hold workflows can issue notices, track acknowledgments, send reminders, and record releases. These capabilities do not replace counsel’s preservation analysis, but they give the team evidence that preservation obligations were communicated and managed.
Processing and early case assessment
Early case assessment benefits from processing automation because it allows the team to see the shape of the data quickly. File inventories, communications maps, date distributions, language identification, near-duplicate groups, and keyword hit reports can inform negotiations about scope and help counsel develop a practical review plan.
Early analysis also reveals problems that are expensive to find later, such as an unusually large number of personal files, missing metadata, encrypted containers, or data from sources outside the original collection plan. Finding those issues before review staffing begins gives the legal team room to adjust.
Review prioritization
Predictive coding, active learning, search-term reports, concept analysis, and email threading can move the most likely responsive documents to the front of the queue. This is valuable when an early production deadline requires counsel to assess key evidence quickly or when the data volume makes linear review impractical.
Prioritization must be monitored. Review managers should track overturn rates, coding consistency, sampling results, and changes in responsiveness rates as the review progresses. If the system is learning from inconsistent coding, it will reproduce that inconsistency at scale.
Production preparation
Production automation can apply Bates numbering, confidentiality designations, redactions, endorsements, load-file settings, and quality checks according to an approved protocol. These are high-consequence tasks. A misplaced confidentiality stamp, failed redaction, or missing family relationship can create avoidable exposure.
Automation improves speed, but production still requires a final human review of exceptions, redaction validation, document counts, and delivery specifications. The best process combines platform controls with a production team that understands the receiving party’s requirements and the governing order.
Defensibility Depends on Process, Not Software Alone
A platform can generate reports, but reports are meaningful only when the underlying process is sound. Legal teams should be able to explain why particular custodians were selected, how sources were collected, which filters were applied, how duplicate handling worked, who changed search terms, and how quality control was performed.
That requires written protocols and disciplined documentation. Matter teams should establish naming conventions, access controls, escalation paths, review instructions, and change-management procedures before the review population expands. If a search term is modified or a date range changes, record why. If a reviewer identifies a new issue, update the coding guidance and communicate the change to the team.
Security is equally central. Discovery data often includes trade secrets, personal information, financial records, health information, privileged communications, and government-sensitive material. Automation should operate within controlled permissions, secure transfer procedures, and clearly defined data retention practices. Efficiency has little value if it compromises confidentiality or custody.
Connecting Digital Discovery With Physical Evidence
Many matters still involve paper files, legacy records, handwritten notes, oversized exhibits, and mixed collections that arrive in bankers boxes as well as on devices. Treating paper and electronic evidence as separate projects can create duplicate work and fragmented tracking.
A coordinated workflow can scan paper records, apply document-level identifiers, capture searchable text, and load the material into the same review environment as electronically stored information. When appropriate, Bates numbering and exhibit preparation can be planned across both formats rather than recreated at the end of the matter.
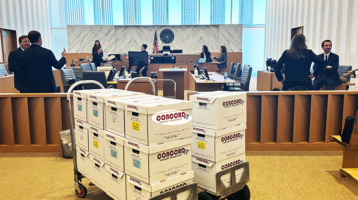
This is particularly useful when trial deadlines approach. The team may need electronic productions, hearing binders, deposition exhibits, demonstratives, and court-ready paper sets on short notice. A provider that understands both review workflows and physical trial production can reduce handoffs at the moment precision matters most.
Questions to Ask Before Expanding Automation
Before committing to a new workflow, legal teams should ask whether the data is sufficiently organized for automation to produce useful results. They should also ask who will validate outcomes, how exceptions will be handled, and whether the process can be explained to a skeptical court or regulator.
Consider the following operational questions:
- What decisions will be automated, and which decisions remain with counsel?
- What quality-control samples, reports, and escalation procedures will be required?
- How will the team preserve metadata, family relationships, and chain-of-custody records?
- Can the workflow support both remote review and urgent productions without creating separate data silos?
- Does the service provider have the capacity to respond when collection, review, and trial production overlap?
These questions are more useful than asking whether a tool has artificial intelligence. The relevant issue is whether the full process improves speed without weakening defensibility.
Build Automation Around the Matter, Not the Other Way Around
Effective eDiscovery automation reflects the facts, legal issues, data sources, and timetable of a specific matter. It does not force every case through the same sequence of tools. A disciplined team may use limited automation for a focused collection and advanced analytics for a multijurisdictional investigation, while applying the same standards for security, documentation, and quality control in both.
For high-stakes matters, the practical advantage comes from having experienced people, proven workflows, and production capacity working together. Concord Document Technologies supports that model with eDiscovery, forensic collection, attorney review support, scanning, legal copying, and trial exhibit production for teams that need executional certainty.
The right automation plan should leave counsel with fewer repetitive tasks, clearer visibility into the evidence, and a defensible record of how the work was done.